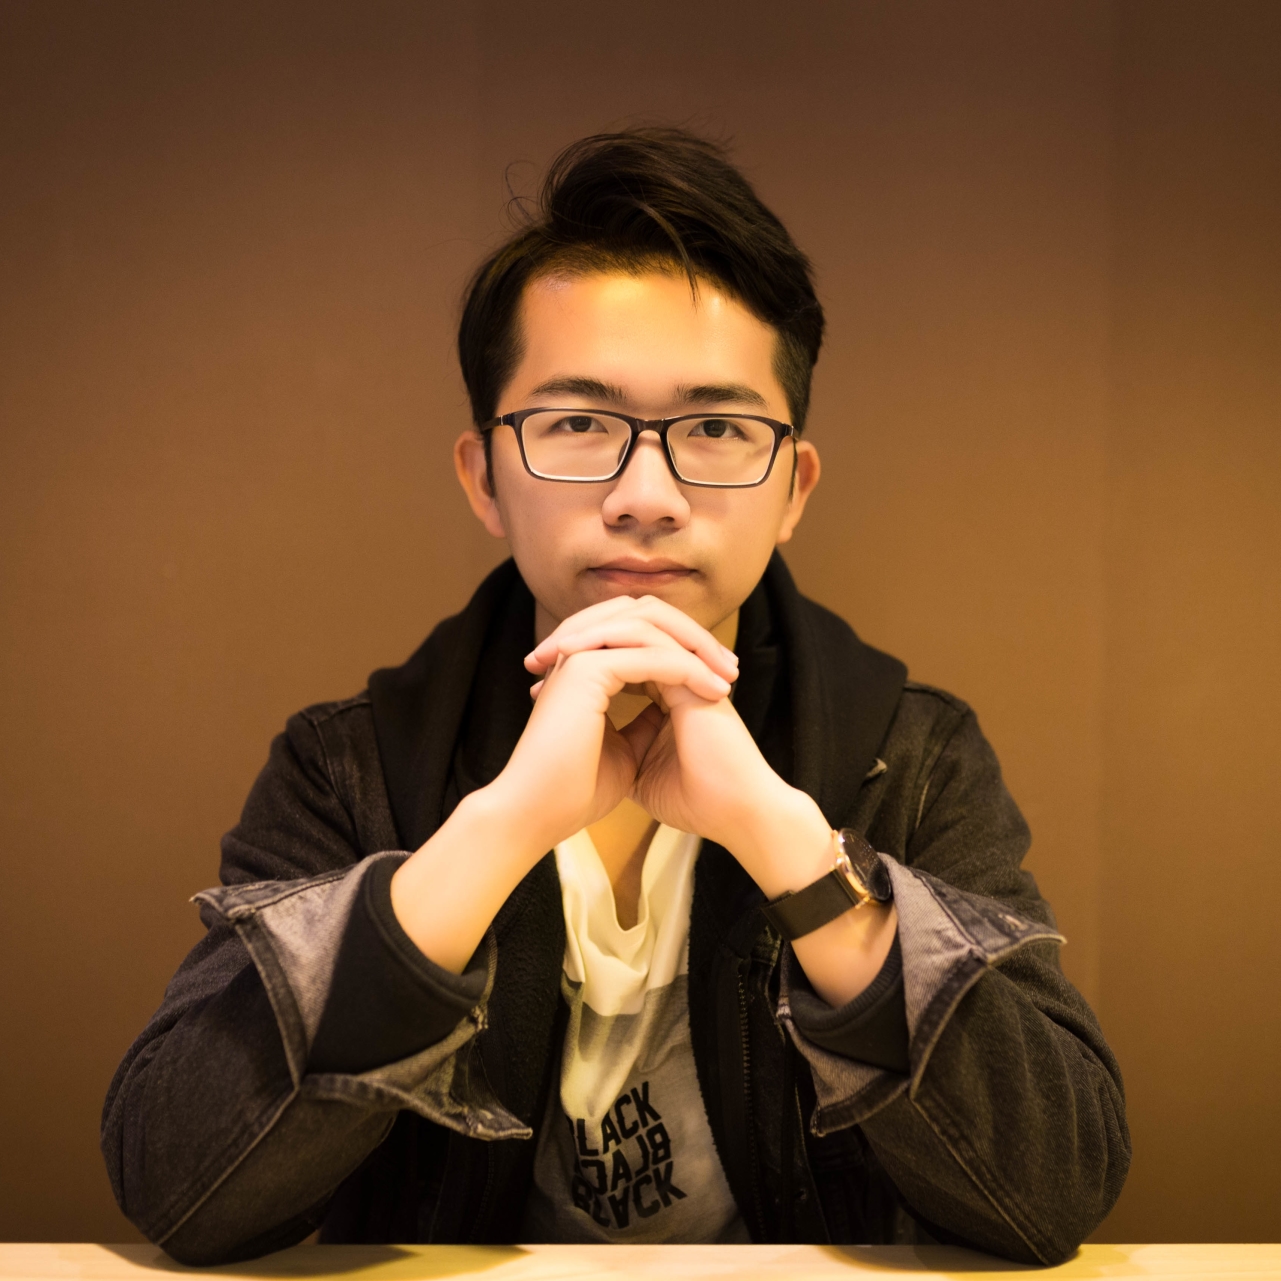
Xiong-Hui Chen
Researcher at Qwen Team.
Joint Postdoc at PKU and Alibaba
Ph.D. in LAMDA Group, Nanjing University
Supervisor: Prof. Yang Yu
Email: xiong-hui.chenn [at] outlook.com, chenxh [at] lamda.nju.edu.cn
The Qwen Team is hiring! We are looking for researchers and engineers who are passionate about developing (1) Next-Gen Robotics Foundation Model; (2) More efficient RL algorithms/infra. If you are interested in exploring this opportunity with us, please contact me at the email addresses above.
[ Google scholar ] [ DBLP ] [ Research gate ] [ Github ] [ Twitter ] [ Zhihu ] [ LinkedIn ]
I obtained my Ph.D. degree from Nanjing University, under the supervision of Prof. Yang Yu, and as a member of the LAMDA Group, led by Prof. Zhi-Hua Zhou. Before my doctoral studies, I received my B.Sc. degree in Software Engineering from Southeast University in 2018. In September 2018, I was admitted to pursue an M.Sc. degree at Nanjing University under the supervision of Prof. Yang Yu. I continued my research as a Ph.D. student from September 2020. From October 2023, I have been a visiting researcher in the UK, working with Prof. Yali Du at King’s College London and Prof. Jun Wang at University College London.
Research Interests:
My research focuses on reinforcement learning (RL) and foundation models for real-world decision-making. My recent work spans embodied foundation models, scalable RL for language and vision-language models, and multimodal reasoning and generation. These directions build on my earlier research in sim-to-real transfer, offline RL, causal inference, and environment modeling, with applications in robotics, autonomous driving, recommender systems, and industrial control.
Recent Research (2025–2026)
- Embodied foundation models: Qwen-Robot. The Qwen-Robot series develops foundation models for robotic manipulation (Qwen-RobotManip), navigation (Qwen-RobotNav), and language-conditioned world modeling (Qwen-RobotWorld).
- RL for foundation models. I have been a core contributor to Qwen’s internal RL algorithms, RL loop, and RL climbing pipeline, working with the team throughout its progression from chain-of-thought (CoT) reasoning to vision-language (VL), agentic systems, and coding. I was also a core contributor to the initial design of Qwen’s asynchronous RL infrastructure. Related work includes GSPO for stable and efficient policy optimization, Beyond the 80/20 Rule on high-entropy tokens in RL for reasoning, and ReVal for off-policy, value-based learning with trajectory reuse.
- Multimodal reasoning and generation. Qwen3-VL develops long-context multimodal understanding and reasoning, and Qwen-Image-2.0 unifies image generation and editing.
See the full publication list for papers and technical reports.
News
| Jul 4, 2026 | Our Qwen-Robot Suite is now public, introducing a family of embodied foundation models for robotic manipulation, navigation, and world modeling. |
|---|---|
| Sep 28, 2025 | Our paper Beyond the 80/20 Rule: High-Entropy Minority Tokens Drive Effective Reinforcement Learning for LLM Reasoning was accepted to NeurIPS 2025. |
| Jan 24, 2025 | One Paper is accepted by ICLR 2025 Oral! (AFlow: Automating Agentic Workflow Generation) |
| Dec 24, 2024 | I will host a seminar about “embodied AI for robotics” at 集智俱乐部, welcome to join us [link]. |
| Dec 21, 2024 | Invited talk about “基于强化学习的可泛化大模型策略求解方法的近期进展” at Amazon Cloud, Beijing. |
| Sep 29, 2024 | Invited talk about “Recent Studies on Causal Reinforcement Learning” at 集智俱乐部. [ slides ]. |
Selected publications
* indicates equal contribution; † indicates corresponding author; § indicates project lead.-
ArXiv
-
ArXivGroup Sequence Policy Optimization
[ Link ]In ArXiv. 2025.
Correspondence
Laboratory: Computer Science Building, Xianlin Campus of Nanjing University
Address: Xiong-Hui Chen, National Key Laboratory for Novel Software Technology, Nanjing University, Xianlin Campus Mailbox 603, 163 Xianlin Avenue, Qixia District, Nanjing 210023, China.南京市栖霞区仙林大道163号, 南京大学仙林校区603信箱, 软件新技术国家重点实验室, 210023.